跨数据源计算
本文提供跨数据源计算场景的实施方案,包括配置示例、执行步骤和参数说明。
案例说明
跨越多个数据源的数据进行sql分析计算
案例实现
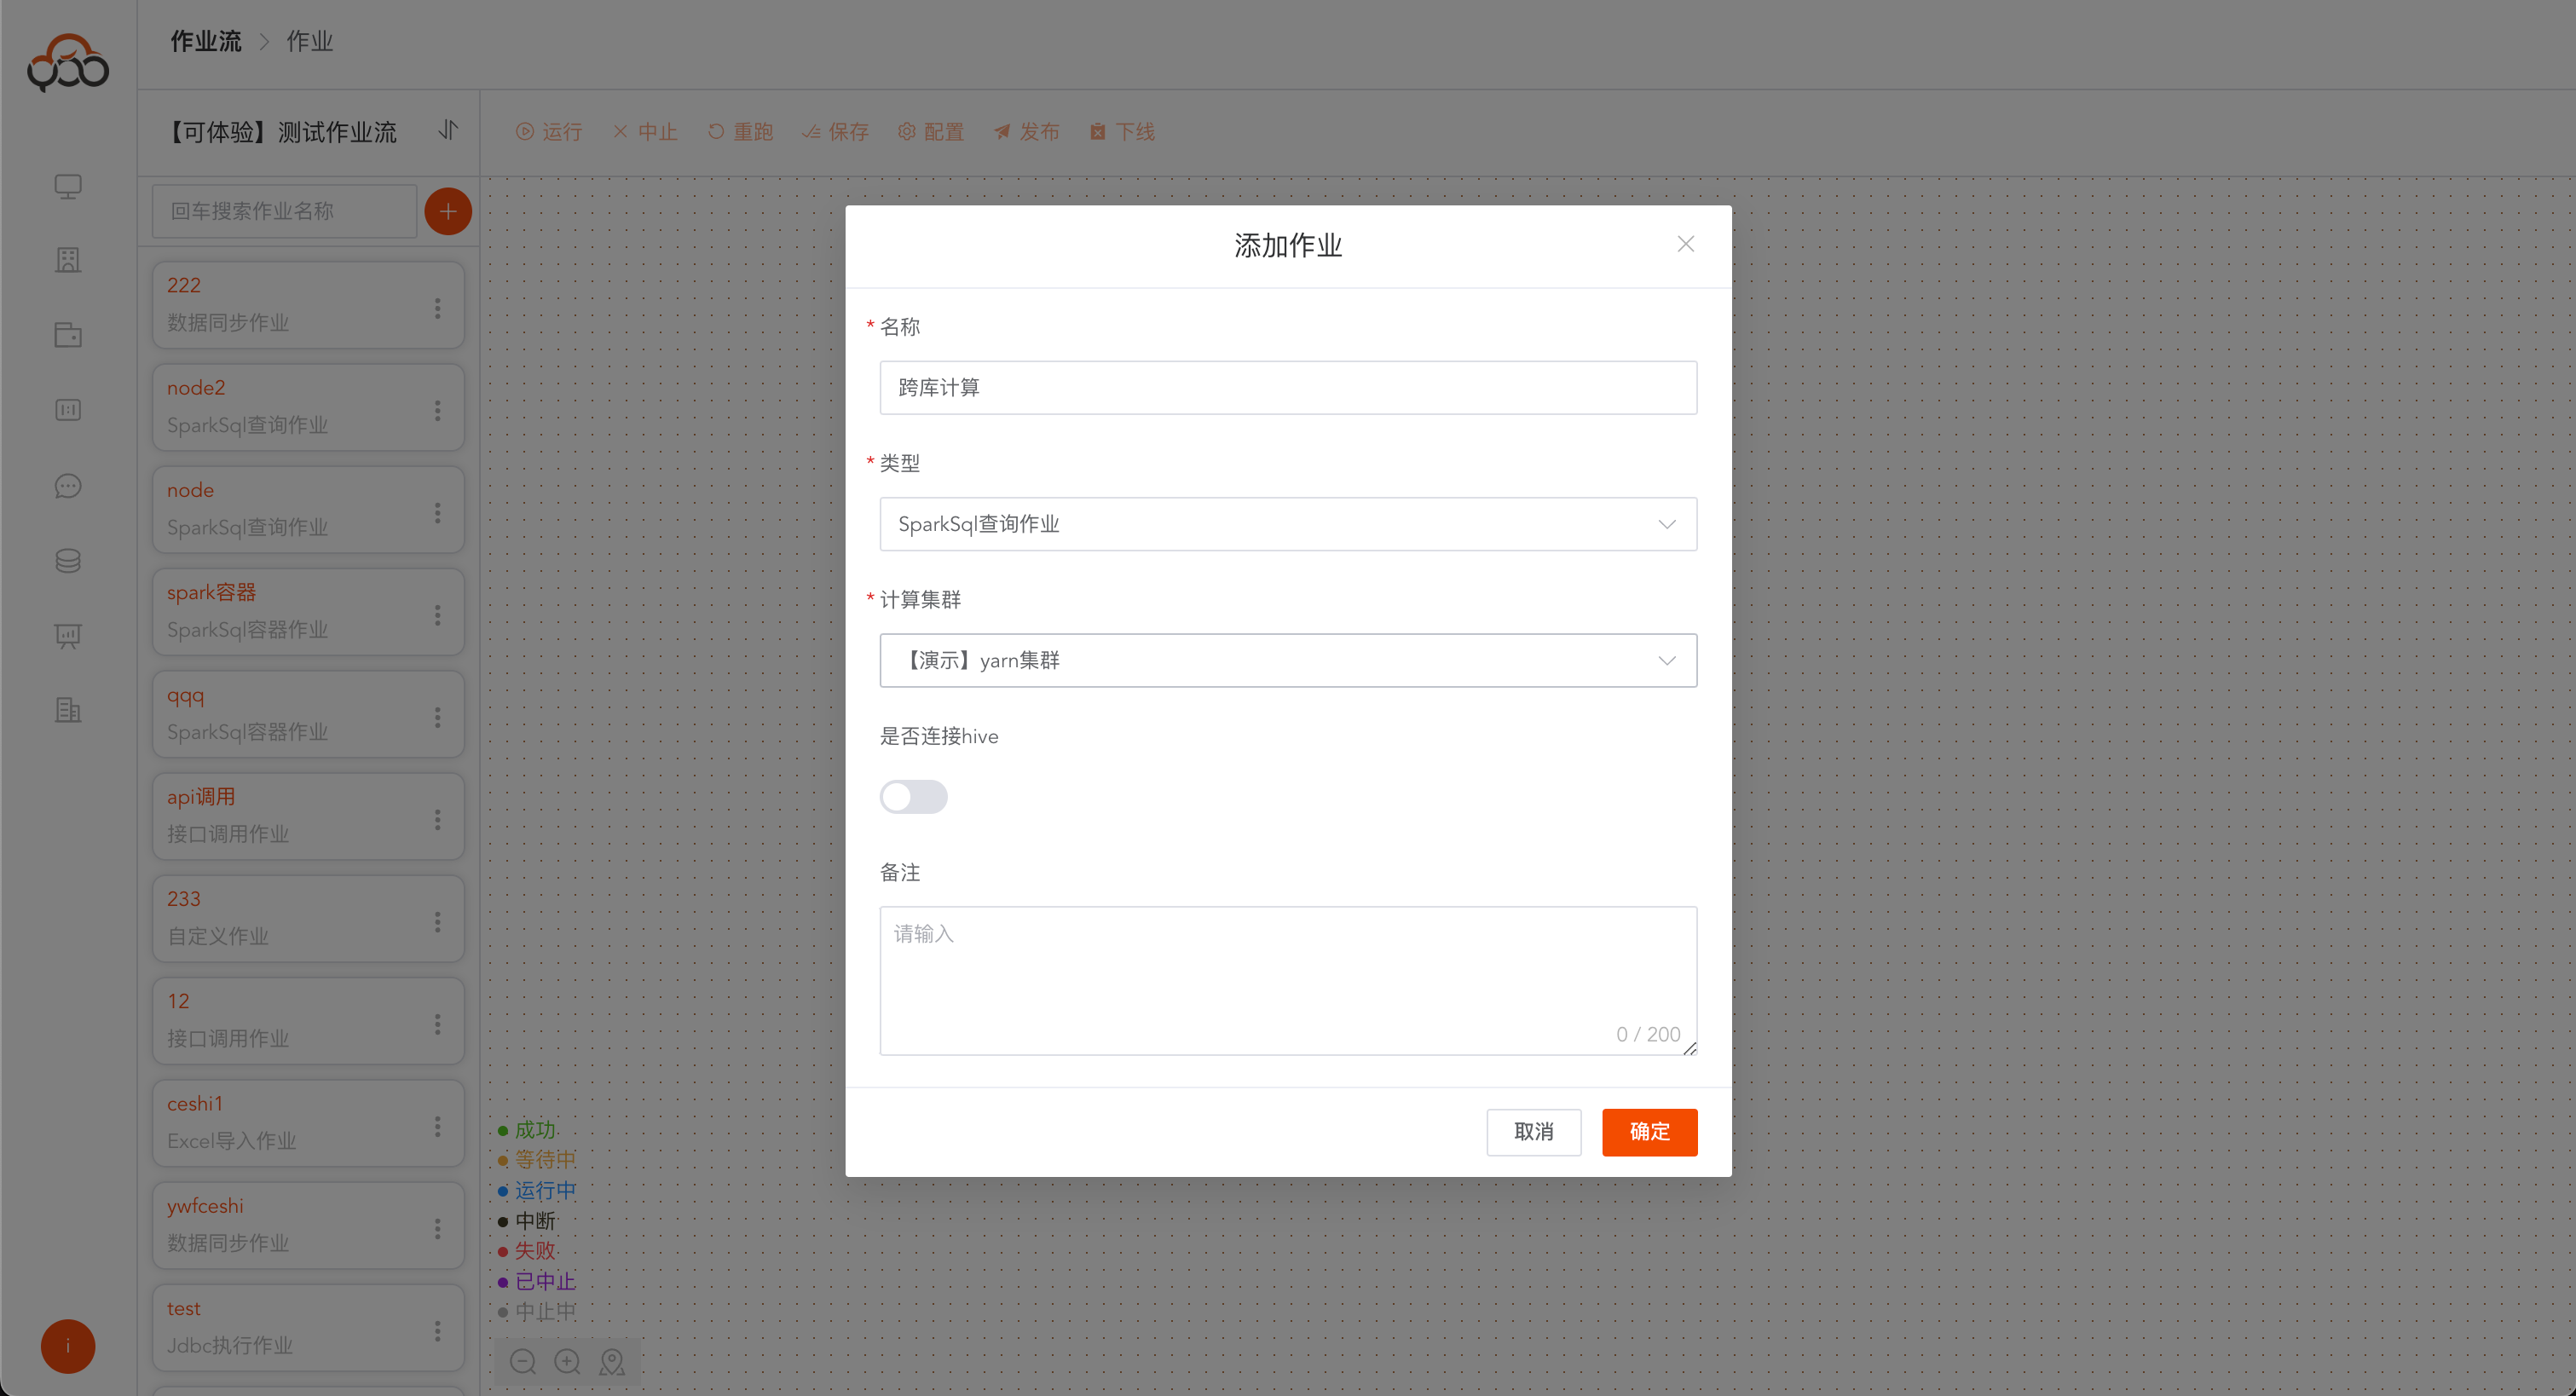
创建
Spark SQL查询作业
SQL 示例
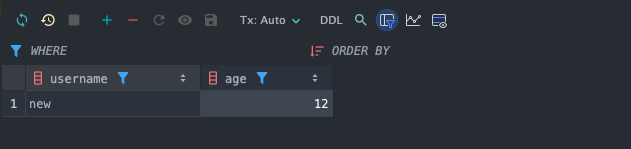
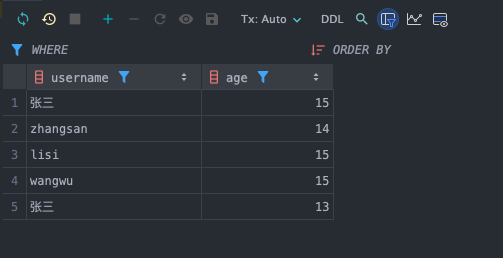
聚合MySQL和PostgreSQL中的数据
-- mysql中数据
CREATE database db1;
USE db1;
CREATE TABLE table1
USING JDBC
OPTIONS (
    driver 'com.mysql.cj.jdbc.Driver',
    url 'jdbc:mysql://127.0.0.1:30102/ispong_db',
    user 'ispong',
    password 'ispong123',
    dbtable 'zqy_users_jdbc'
);

-- postgresql中数据
CREATE database db2;
USE db2;
CREATE TABLE table2
USING JDBC
OPTIONS (
    driver 'org.postgresql.Driver',
    url 'jdbc:postgresql://127.0.0.1:30162/isxcode_db',
    user 'postgres',
    password 'ispong123',
    dbtable 'users'
);

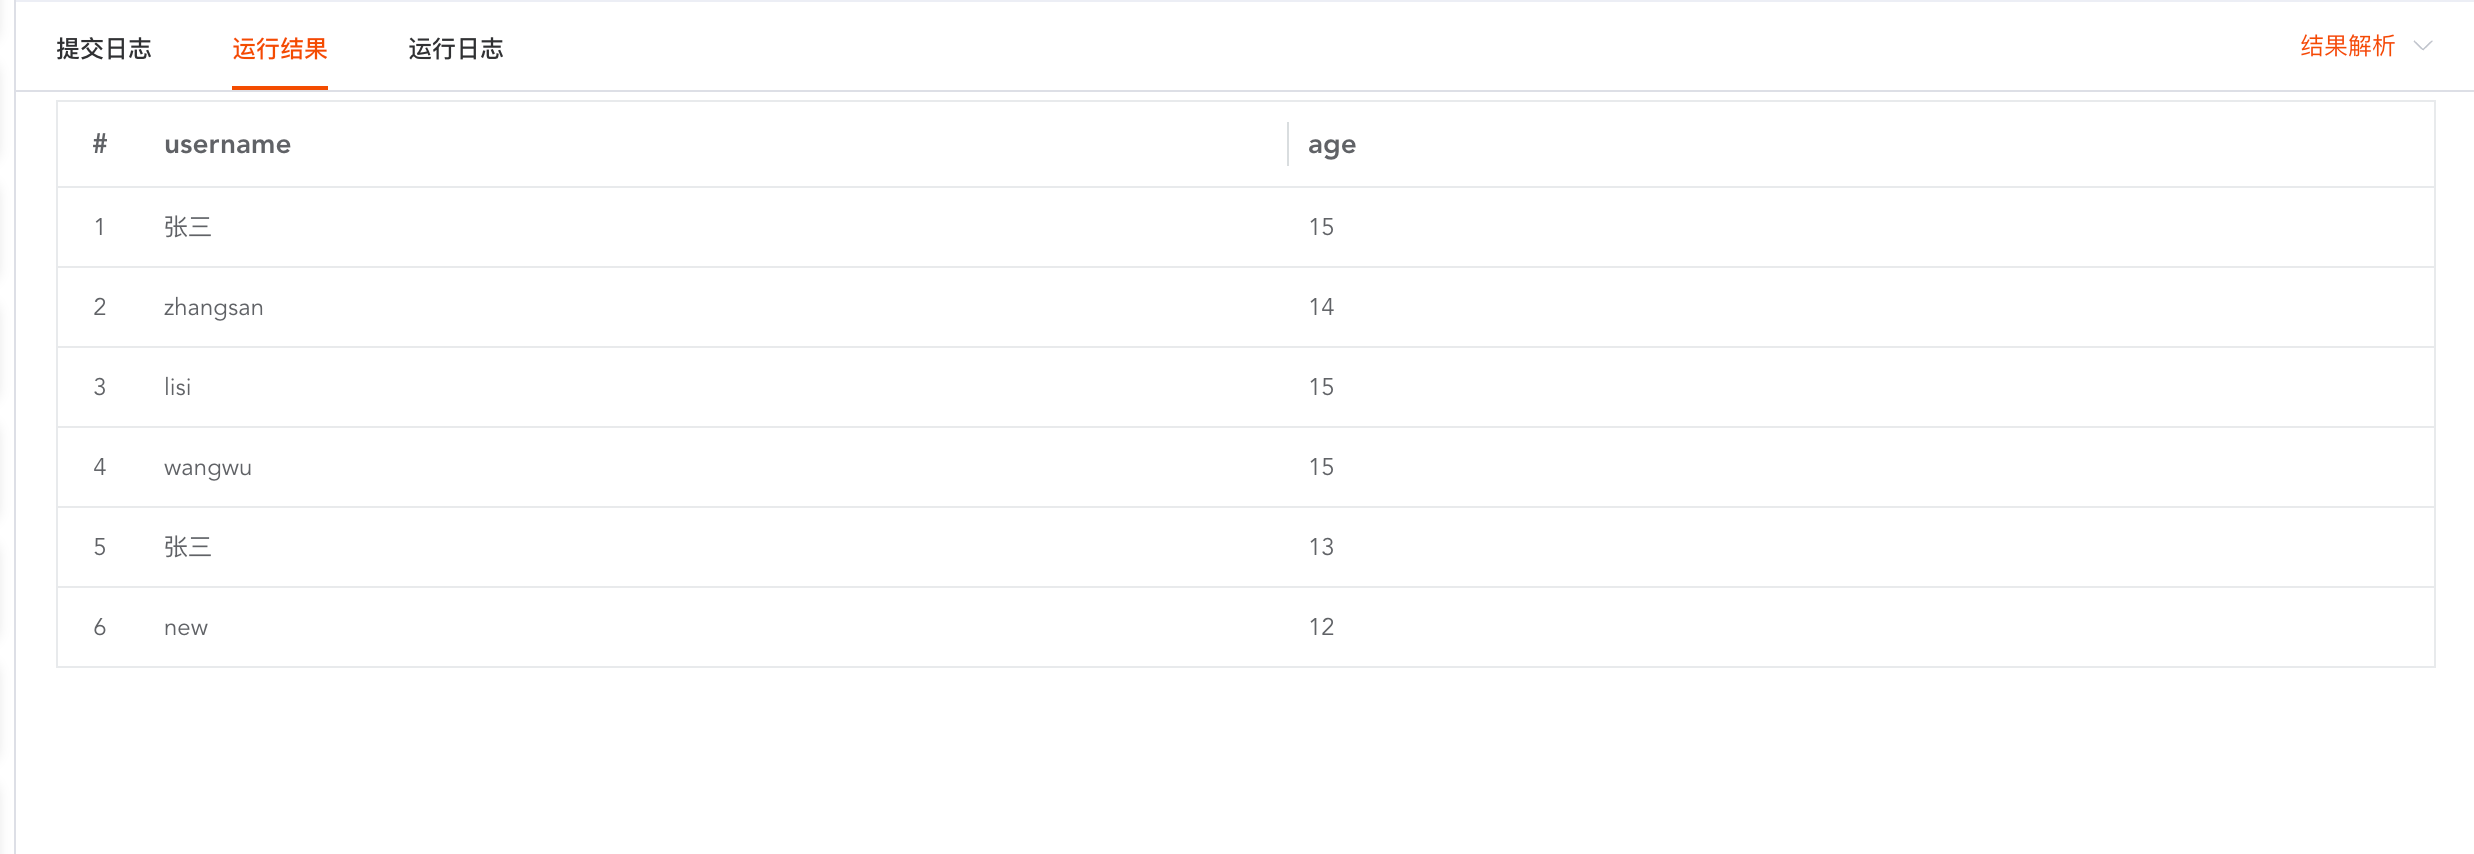
-- 执行计算sql
select * from db1.table1 union all select * from db2.table2;