
Flink integrates Iceberg
This article provides an implementation plan for Flink integrating Iceberg scenarios, including configuration examples, execution steps, and parameter descriptions.
Case
Use flink to add, delete, modify and query Iceberg data
solution
Create
Flink SQL query joband download dependencies
- iceberg-flink-runtime-1.18-1.6.1.jar download
- libthrift-0.9.3.jar download
- libfb303-0.9.3.jar download
- hive-exec-3.1.3.jar download
- hive-Standalone-metastore-3.1.3.jar download
- hive-common-3.1.3.jar download
- hadoop-mapreduce-client-core-3.3.5.jar download
- commons-lang-2.6.jar download
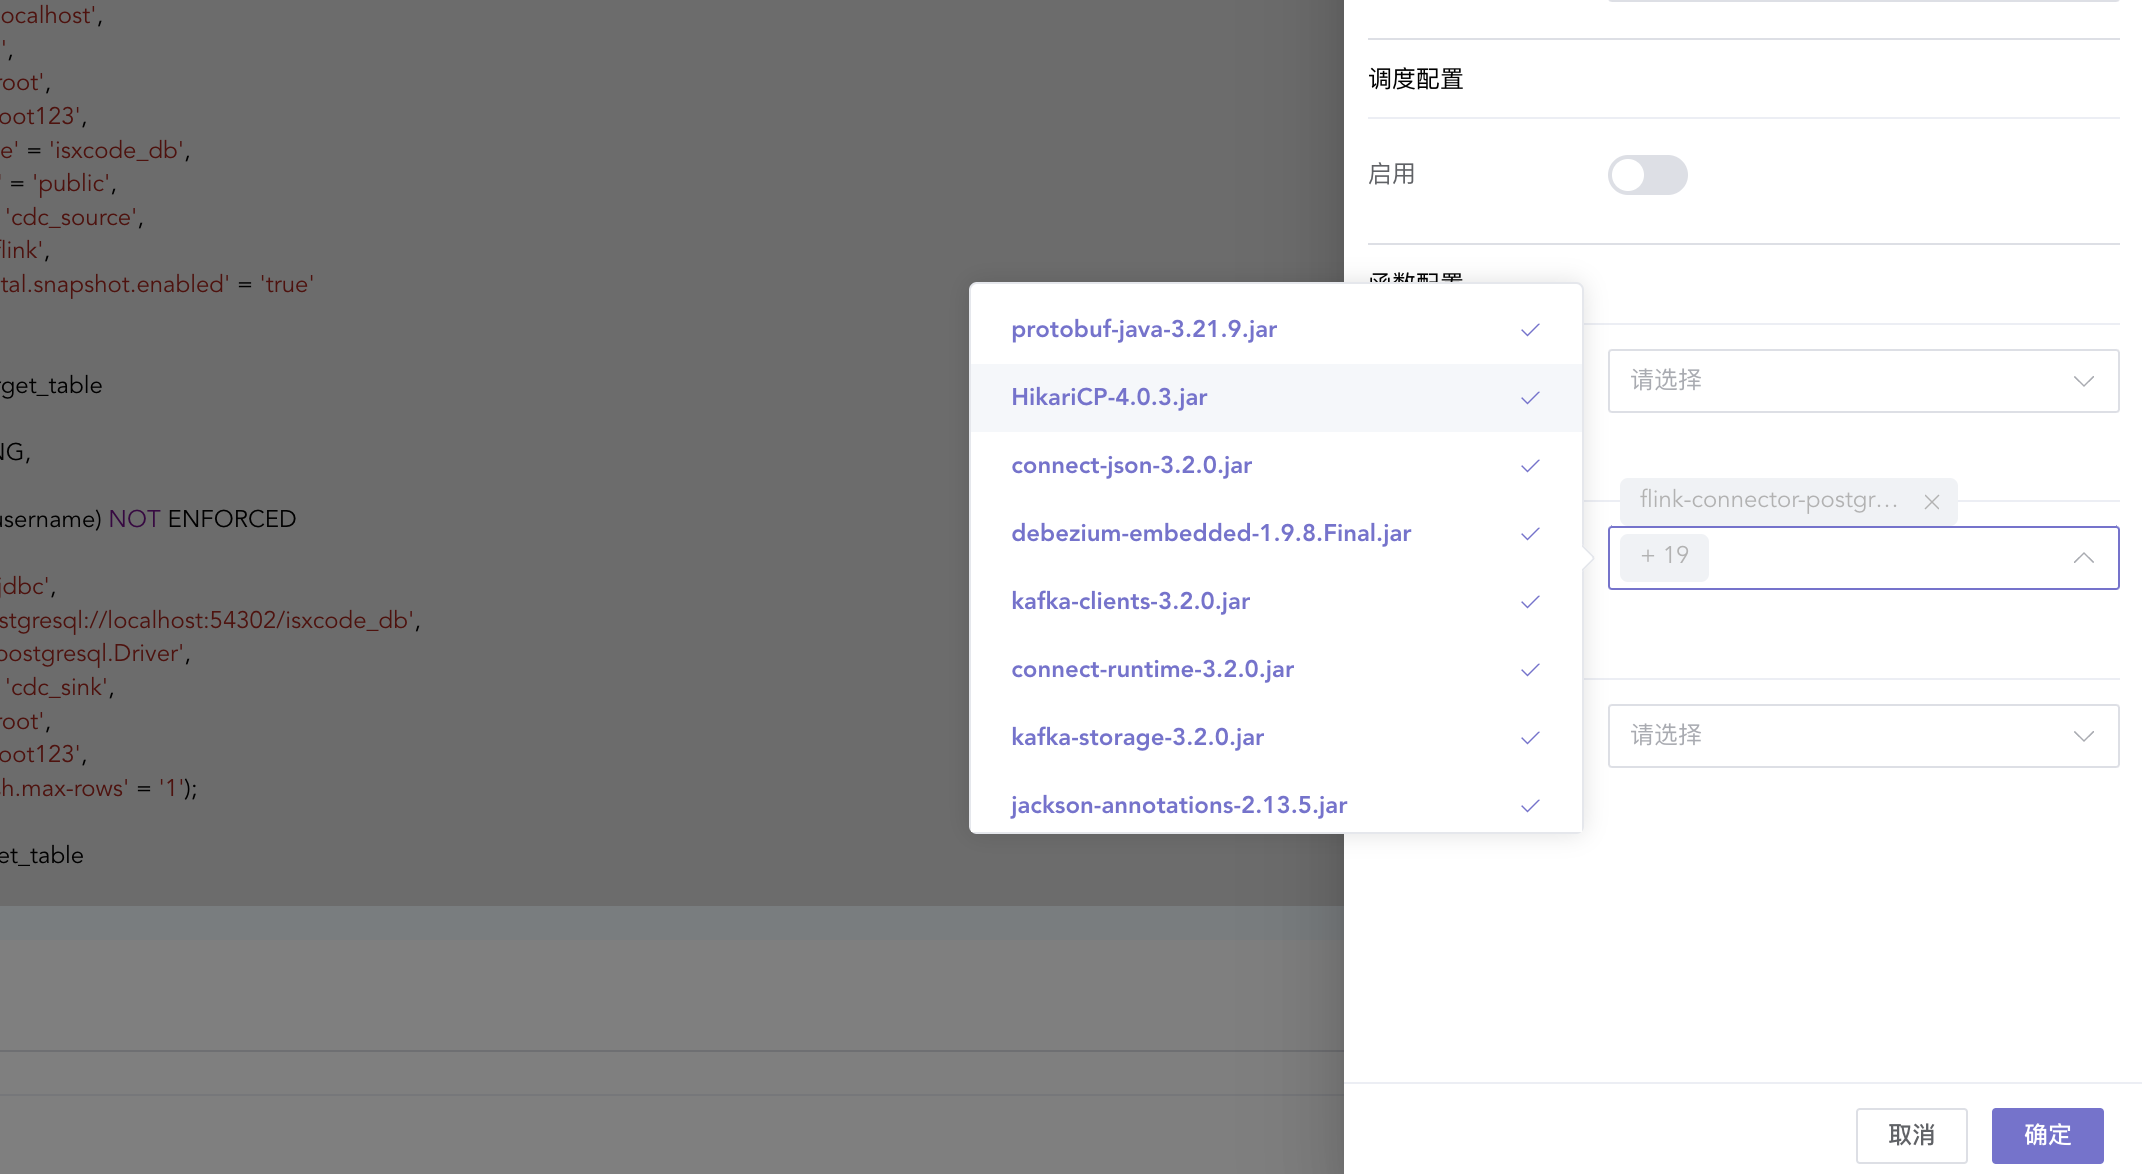
Flink SQL
CREATE CATALOG hive_catalog WITH (
  'type'='iceberg',
  'catalog-type'='hive',
  'uri'='thrift://172.19.189.246:9083',
  'clients'='10',
  'property-version'='1',
  'warehouse'='hdfs://172.19.189.246:9000/user/hive/warehouse'
);

CREATE TABLE IF NOT EXISTS  `hive_catalog`.`ispong_db`.`iceberg_table2` (
    id BIGINT COMMENT 'unique id',
    data STRING
);

-- 删除。更新 需要走批处理模式
INSERT INTO `hive_catalog`.`ispong_db`.`iceberg_table2` VALUES (1, 'a');

INSERT INTO `hive_catalog`.`ispong_db`.`iceberg_table2` VALUES (2, 'b');