
PostgreSQL offline synchronization
This article provides implementation ideas, configuration examples, and verification methods for PostgreSQL offline synchronization scenarios, which can be used as a reference for actual project configuration.
Implement offline synchronization of data from the result table to the target table in PostgreSQL
Case
Offline synchronization of data in t_source to t_target in PostgreSQL
solution
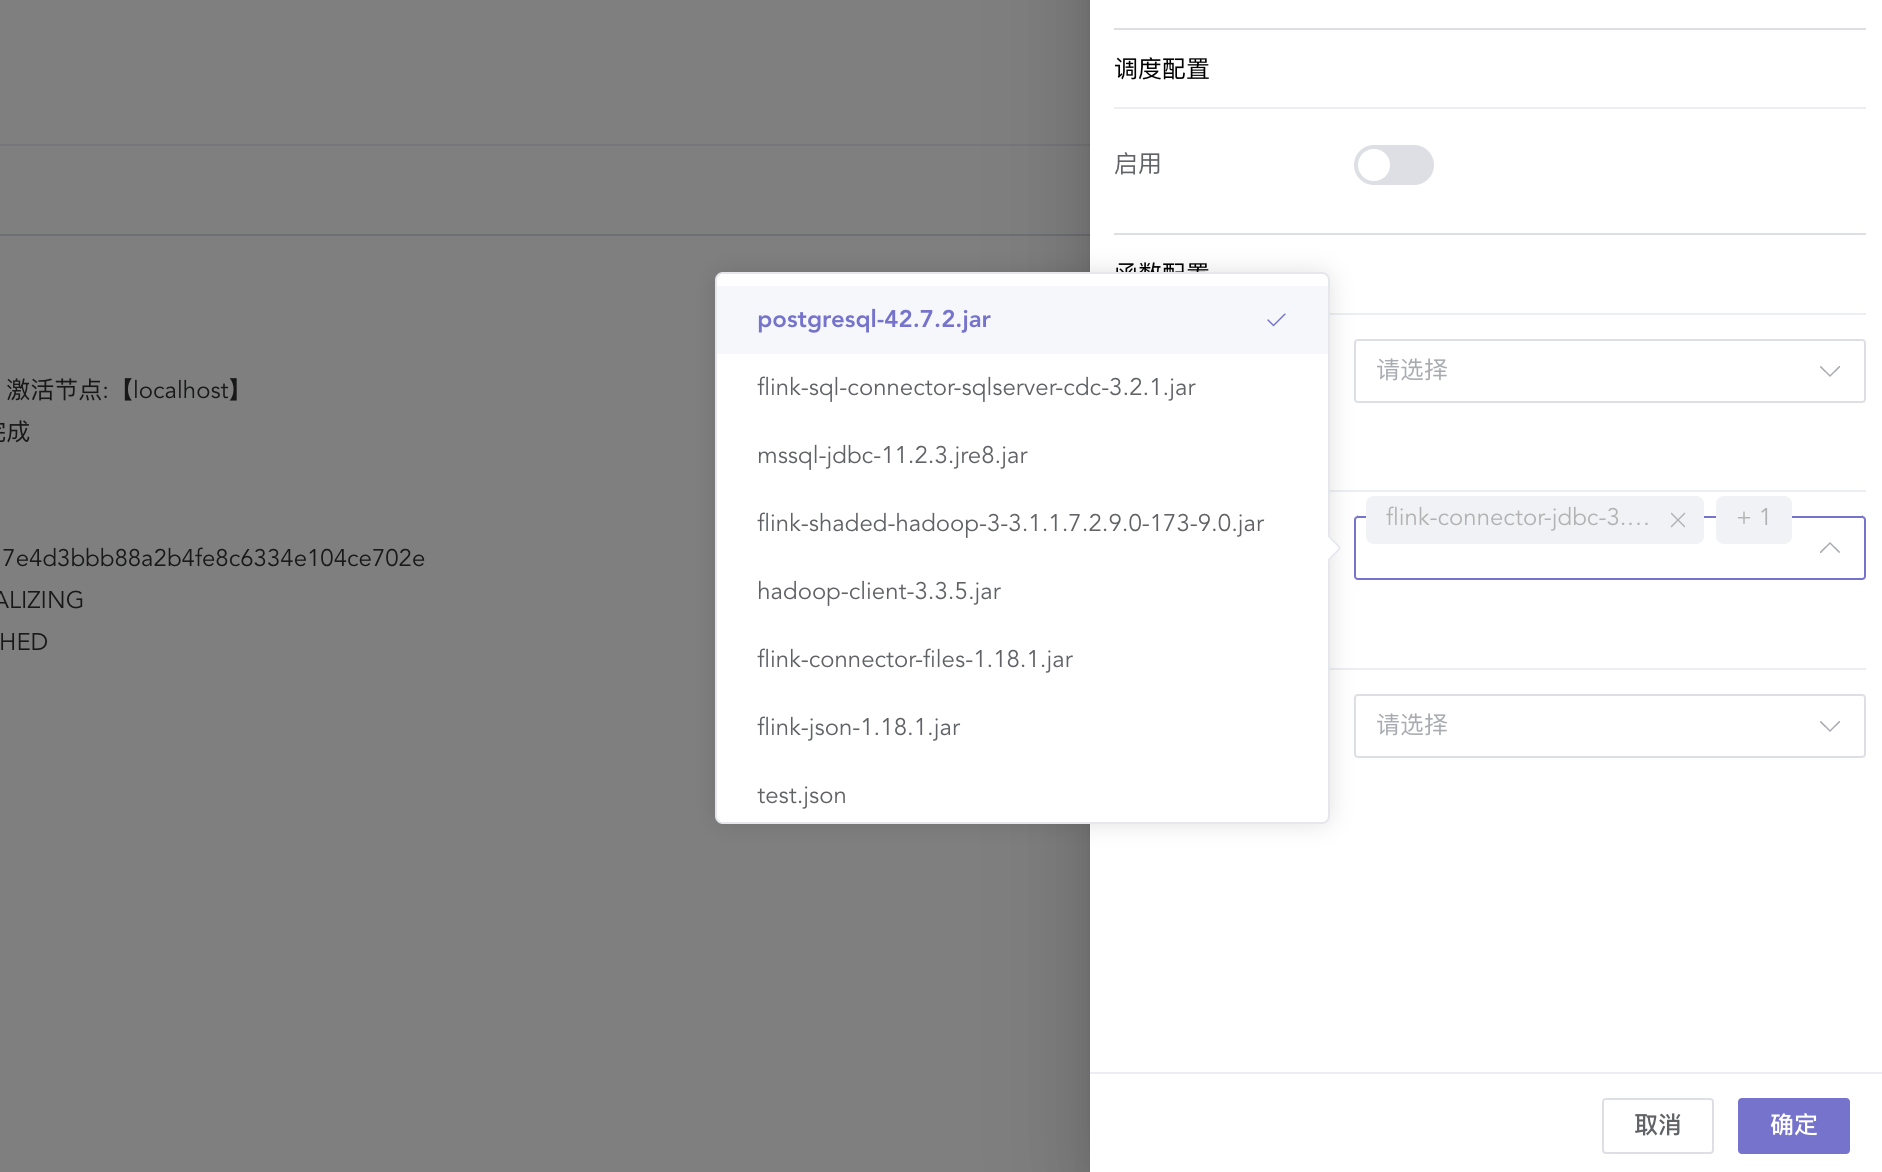
Create a Flink SQL job type and add the following dependencies
CREATE TABLE from_table
(
    username STRING,
    age      INT
) WITH (
      'connector' = 'jdbc',
      'url' = 'jdbc:postgresql://localhost:54302/isxcode_db',
      'driver' = 'org.postgresql.Driver',
      'table-name' = 't_source',
      'username' = 'root',
      'password' = 'root123',
      'scan.fetch-size' = '1'
      );

CREATE TABLE target_table
(
    username STRING,
    age      INT
) WITH (
      'connector' = 'jdbc',
      'url' = 'jdbc:postgresql://localhost:54302/isxcode_db',
      'driver' = 'org.postgresql.Driver',
      'table-name' = 't_sink',
      'username' = 'root',
      'password' = 'root123',
      'sink.buffer-flush.max-rows' = '1');

INSERT INTO target_table
select *
from from_table;
| Configuration items | Description |
|---|---|
| connector | Connection method |
| url | Database connection url |
| driver | Data source driven |
| table-name | table name |
| username | Data source account |
| password | Account password |
| scan.fetch-size | How much data does each operation |
| sink.buffer-flush.max-rows | How many pieces of data are merged into one transaction? |