Compute across data sources
This article provides an implementation plan for cross-data source computing scenarios, including configuration examples, execution steps, and parameter descriptions.
Case description
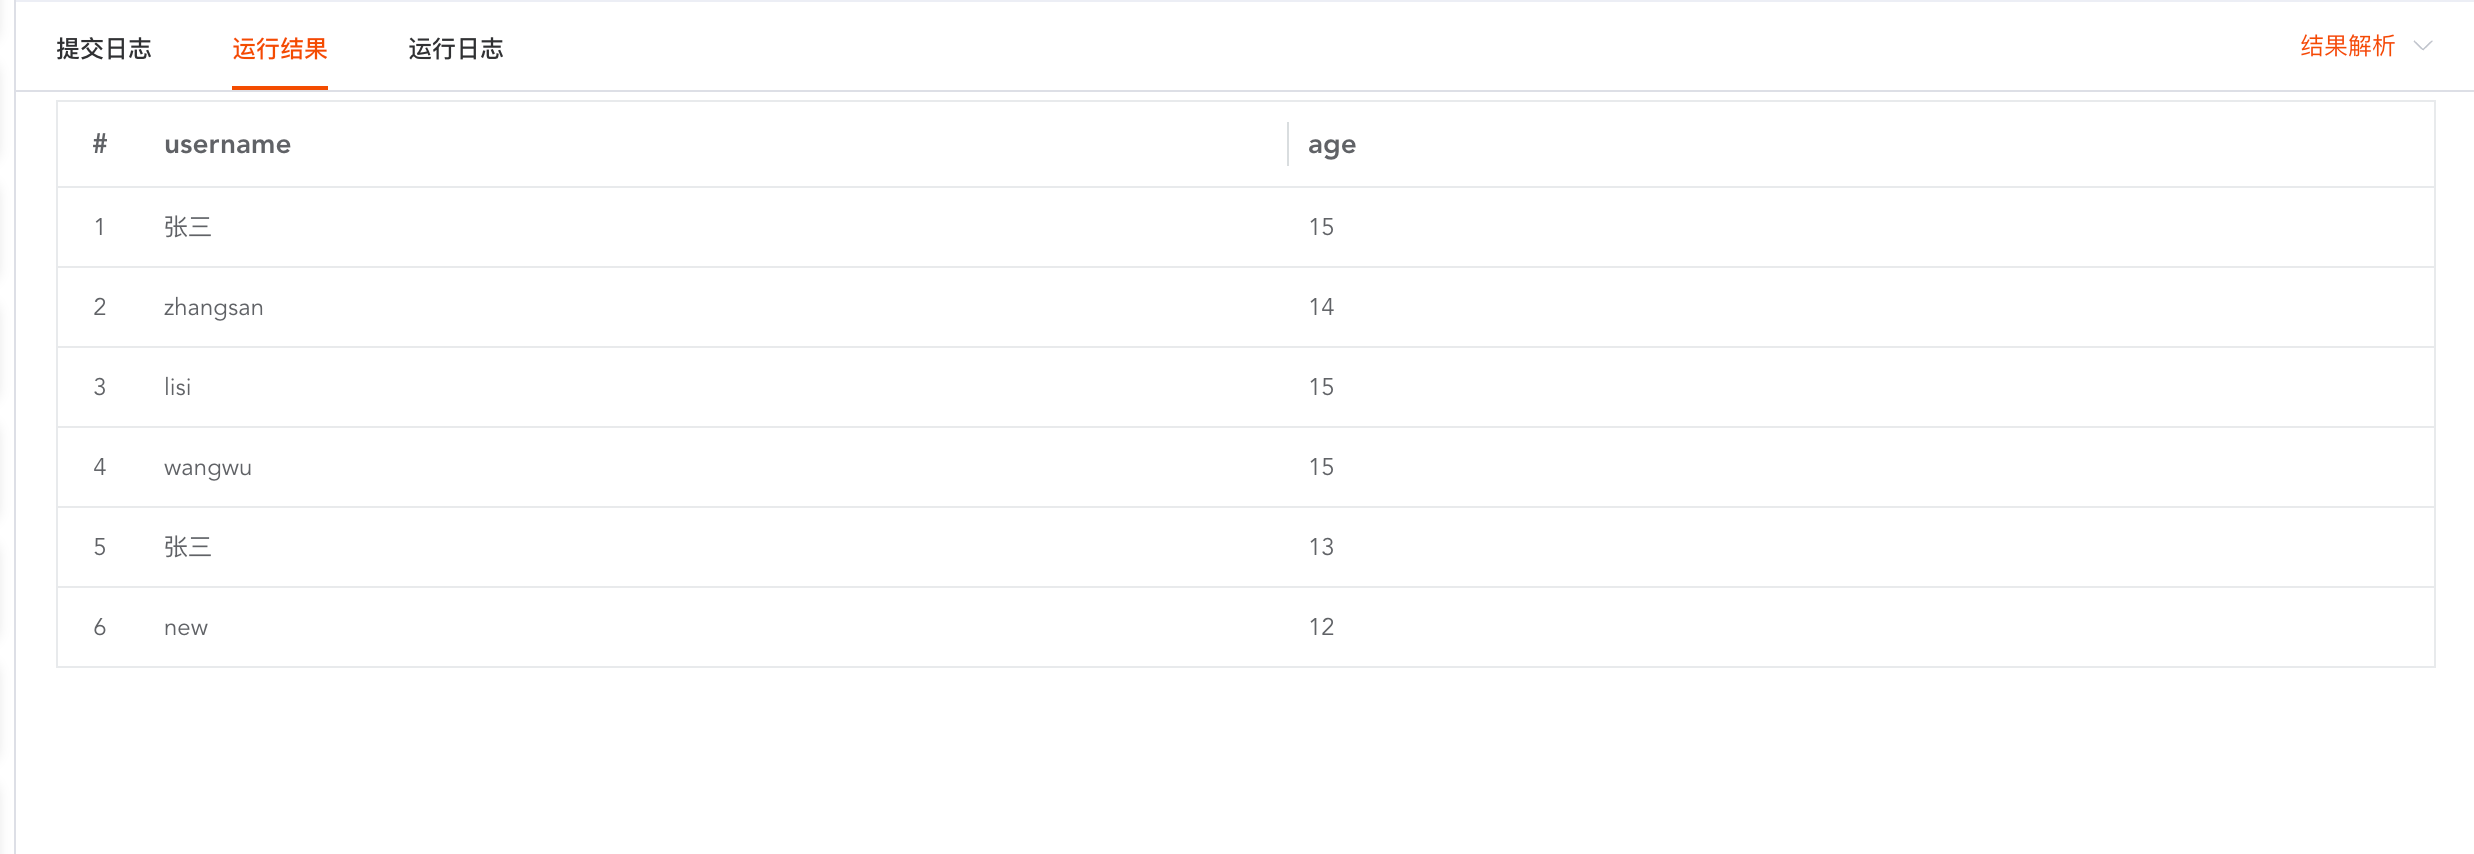
Perform SQL analysis and calculation on data spanning multiple data sources
Case implementation
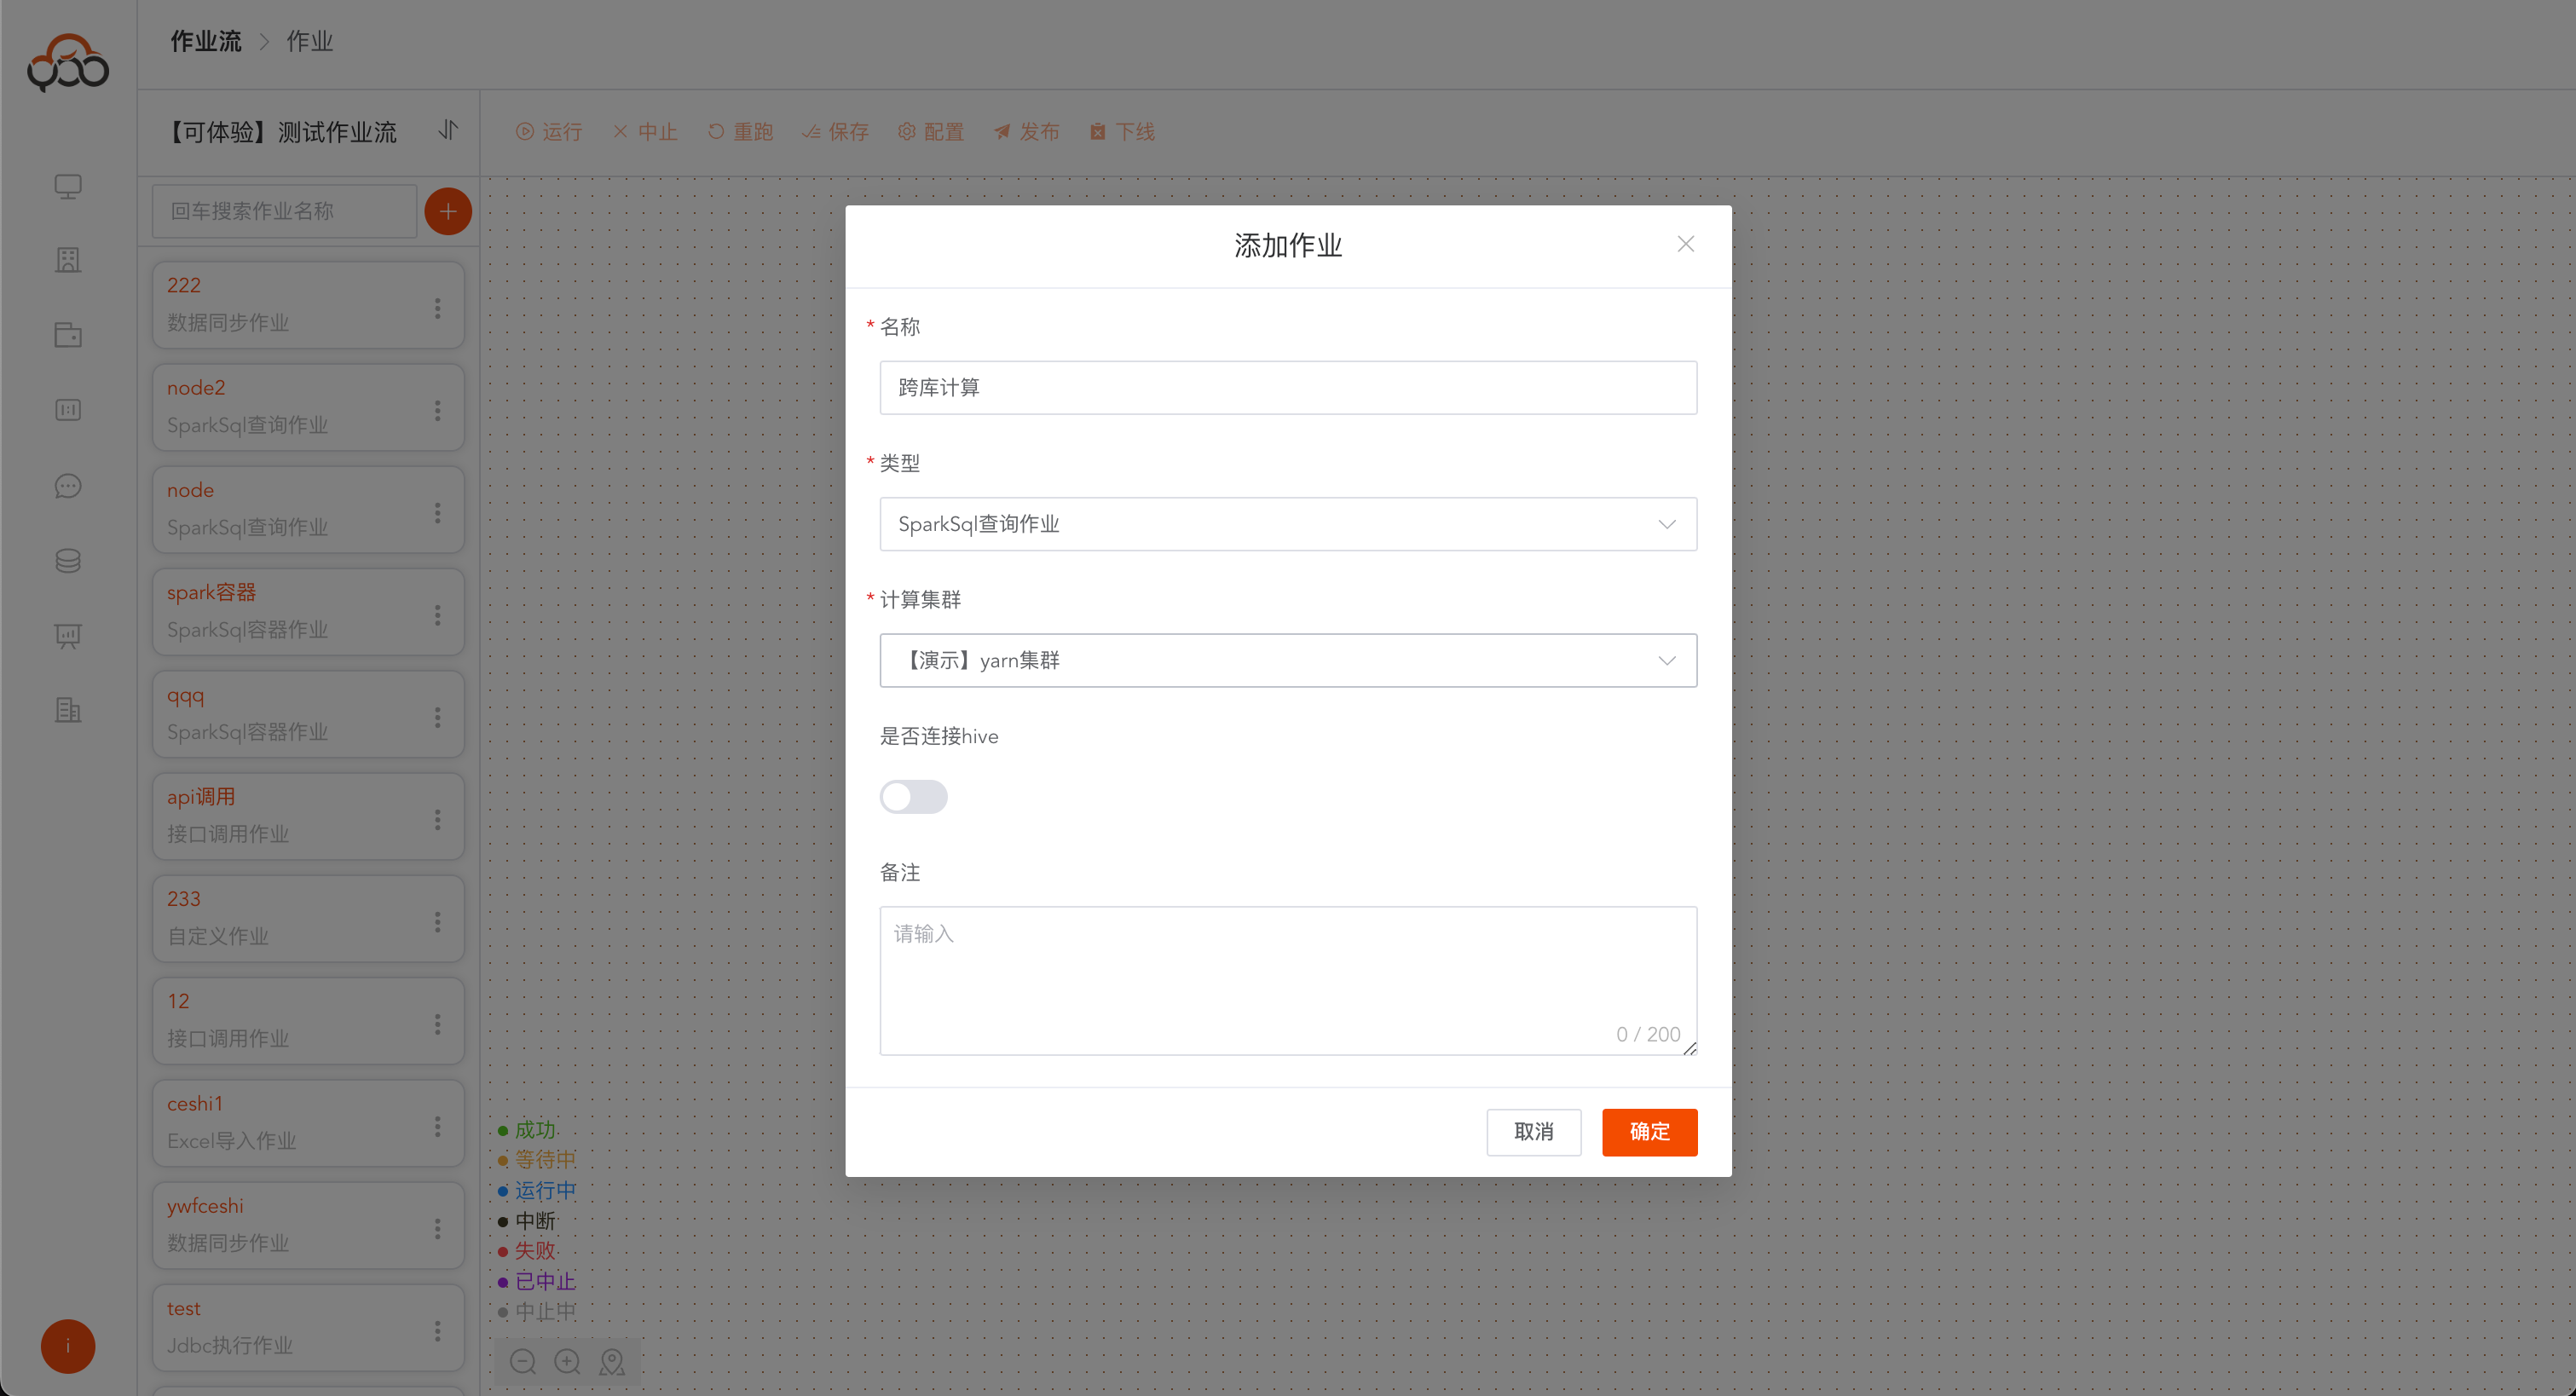
Create a
Spark SQL query job
SQL example
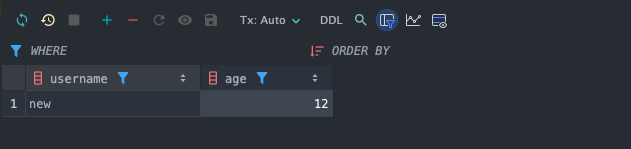
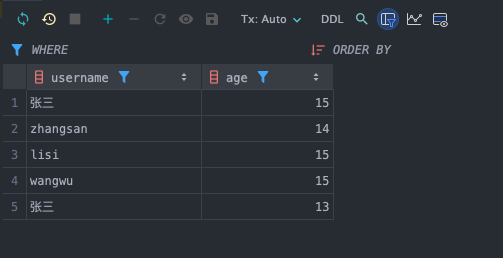
Aggregate data in MySQL and PostgreSQL
-- mysql中数据
CREATE database db1;
USE db1;
CREATE TABLE table1
USING JDBC
OPTIONS (
    driver 'com.mysql.cj.jdbc.Driver',
    url 'jdbc:mysql://127.0.0.1:30102/ispong_db',
    user 'ispong',
    password 'ispong123',
    dbtable 'zqy_users_jdbc'
);

-- postgresql中数据
CREATE database db2;
USE db2;
CREATE TABLE table2
USING JDBC
OPTIONS (
    driver 'org.postgresql.Driver',
    url 'jdbc:postgresql://127.0.0.1:30162/isxcode_db',
    user 'postgres',
    password 'ispong123',
    dbtable 'users'
);

-- 执行计算sql
select * from db1.table1 union all select * from db2.table2;